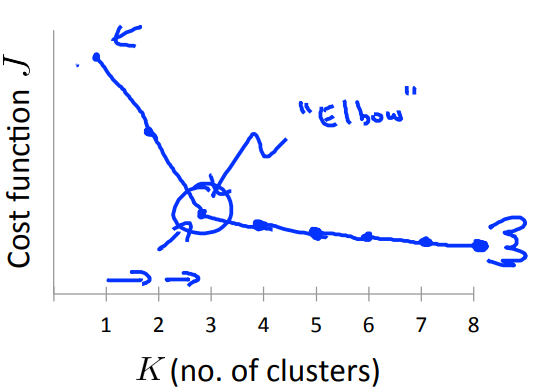
Elbow Method
노트 편집 ↗
링크된 언급
2K-means silhouette score Elbow Method
Choosing the Number of Clusters: Elbow Method K-means++ center 초기값 선택 알고리즘이다.
함께 보면 좋은 글
distortion
Distortion 은 clustering 에서 data point 와 자신이 속한 cluster center 사이의 거리 기반 cost 를 말한다. K-means 에서는 각 point 가 배정된 centroid 와 얼마나 떨어져 있는지를 평균적으로 측정한다.
K-means
k : 클러스터 개수 (사용자에 의해 정의됨) N : 객체 개수 r: 수렴할때 까지 반복한 iteration 횟수 D : 객체의 차원 수 (window 를 이용한 clustering 의 경우, window 길이)
K-prototype
K-prototype 은 k-means 와 k-mode 를 결합하여 수치적 데이터와 범주적 데이터가 모두 있는 데이터 세트를 처리하는 클러스터링 알고리즘 (clustering)
Hierarchical Clustering
객체 간 pairwise distance matrix 를 이용해서, 비슷한 객체 간 중첩된 계층 그룹을 생성하는 방법
DBSCAN
DBSCAN은 density 기반 clustering 알고리즘이다. 가까운 이웃이 충분히 많은 point를 core point로 보고, core point들이 이어진 dense region을 cluster로 만든다.
silhouette score
clustering 적용 후, 데이터가 얼마나 잘 분류되었는지 수치적으로 확인할 수 있는 값
k-Nearest Neighbors
어떤 문제를 푸냐에 따라 방식이 달라진다: 분류 또는 회귀.
t-Stochastic Nearest Embedding
t-Stochastic Nearest Embedding 는 vector visualization 을 위하여 자주 이용되는 차원 축소 알고리즘이다.
unsupervised learning
clustering K-means DBSCAN anomaly detection One-class support vector machine Isolation Forest dimensionality reduction machine learning/dimensionality reduction/Principal...
metric learning
metric learning 은 데이터 포인트 간의 거리를 측정하는 방법을 학습하는 기법입니다.