Zzong's Notes

방문

Home

❯

논문

❯

Bandit

❯

Recommender systems using LinUCB - A contextual multi-armed bandit approach

Recommender systems using LinUCB - A contextual multi-armed bandit approach

최초 작성 2026-06-14마지막 수정 2026-08-29읽는 데 1분

노트 편집 ↗
  • Metadata
    • Tag: Contextual Bandit, Thompson sampling, LinUCB, Multi-Armed Bandit
    • Link: https://towardsdatascience.com/recommender-systems-using-linucb-a-contextual-multi-armed-bandit-approach-35a6f0eb6c4
    • Related Reference: git_issue_Contextual Bandit 을 활용한 개인화추천 성능 고도화 실험, A Contextual-Bandit Approach to Personalized News Article Recommendation
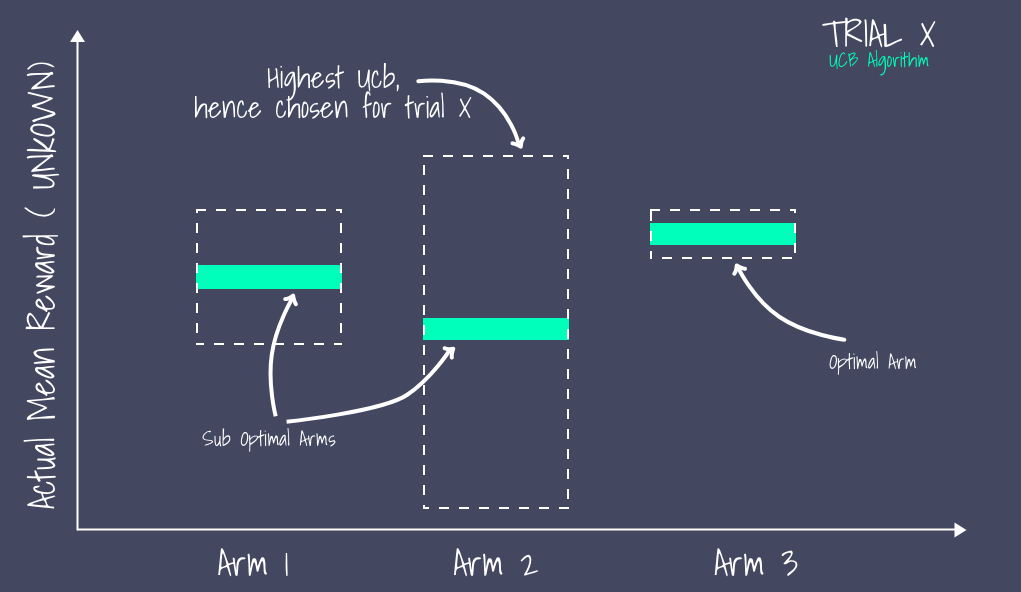
      • Even though the recorded mean award achieved for Arm 3 is higher, the algorithm selects arm 2 because of the uncertainty of its potential and updates its confidence bound for future trials.

함께 보면 좋은 글

A Contextual-Bandit Approach to Personalized News Article Recommendation

사용자와 콘텐츠 정보를 활용한 개인화 웹 서비스 (광고, 뉴스 등) 를 제공하는 것은 다음과 같은 두 가지 이유로 어렵다. 1. web service is featured with dynamically changing pools of content, rendering traditional collaborative...

Top-K Contextual Bandits with Equity of Exposure

Probability Ranking Principle 에 의하면 top-K items 을 greedy 하게 rank 하는것이 optimal 함

Optimal Regret Analysis of Thompson Sampling in Stochastic Multi-armed Bandit Problem with Multiple Plays

Thompson sampling is an old heuristic that has a spirit of Bayesian inference and selects an arm based on posterior samples of the expectation of each arm.

An Asymptotically Optimal Primal-Dual Incremental Algorithm for Contextual Linear Bandits

optimism principle 에 기반한 알고리즘은 문제에 대한 구조를 exploit 하는데 실패하여 점근적으로 suboptimal 결과를 보임 context 분포와 exploration policy 가 나눠지도록 (decoupled) regret lower bound 를 reformulate 하여,...

Mortal Multi-Armed Bandits

일반적인 Multi-Armed Bandit 은 arm 이 사라지지 않는다고 가정한다. Mortal MAB 는 arm 마다 수명이 있어서 일정 시점이 지나면 arm 이 죽고 (더 이상 당길 수 없고), 새 arm 이 계속 들어오는 상황을 다룬다. 광고나 뉴스처럼 후보가 계속 바뀌는 추천 문제가 이 설정에 해당한다.

Contextual Combinatorial Bandit and its Application on Diversified Online Recommendation

http://www.chenshouyuan.com/papers/sdm14.pdf

Deep Bayesian Bandits Showdown - An Empirical Comparison of Bayesian Deep Networks for Thompson Sampling

이 논문의 main research question: how approximated model posteriors affect the performance of decision making via Thompson Sampling in contextual bandits.

Deep Bayesian Bandits - Exploring in Online Personalized Recommendations

Contextual Bandit + Bootstrapped Neural Network 로 CTR 예측의 불확실성을 추정하여 광고 추천에서 exploration을 수행.

Burst-induced Multi-Armed Bandit for Learning Recommendation

해결하려는 문제: a non-stationary and context-free Multi-Armed Bandit problem, 유저나 아이템에 대한 어떠한 정보가 없는 경우

Interactively Optimizing Information Retrieval Systems as a Dueling Bandits Problem

papers/recommender system/Online learning to rank for information retrieval